樣本統計量與母體比較
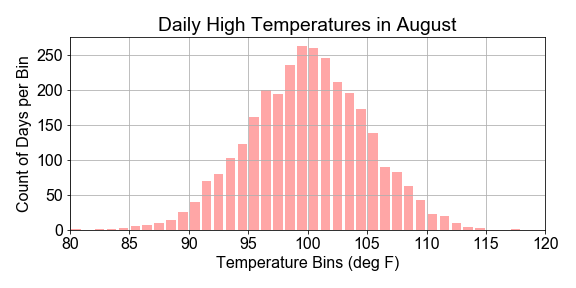
在這個練習中,你會使用已預先載入的 population。你將隨機從母體抽樣來建立一個 sample。接著你會計算該樣本的平均數與標準差,檢驗這個樣本是否能代表母體。你的目標是觀察樣本統計量是否與母體統計量相同或非常接近。
本練習屬於課程
Python 線性建模入門
練習說明
- 計算並印出
population資料的平均數與標準差。 - 使用
np.random.seed()方法將numpy的偽隨機取樣器種子設為42。 - 使用
np.random.choice()建立size=31的sample,其中 size 代表從population抽取的點數。 - 計算並印出
sample的平均數與標準差,並比較樣本與母體的統計量,看看是否有差異。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
# Compute the population statistics
print("Population mean {:.1f}, stdev {:.2f}".format( population.____(), population.____() ))

# Set random seed for reproducibility
____.____.____(42)

# Construct a sample by randomly sampling 31 points from the population
sample = np.____.____(____, size=31)

# Compare sample statistics to the population statistics
print("    Sample mean {:.1f}, stdev {:.2f}".format( sample.____(), sample.____() ))