CV 微調:資料集準備
在這個練習中,你要為訓練準備 Stanford Cars 資料集。你會使用 datasets 函式庫來切分資料集,並套用前處理轉換。此資料集包含 8k 張帶標籤的影像,涵蓋 196 款車型:
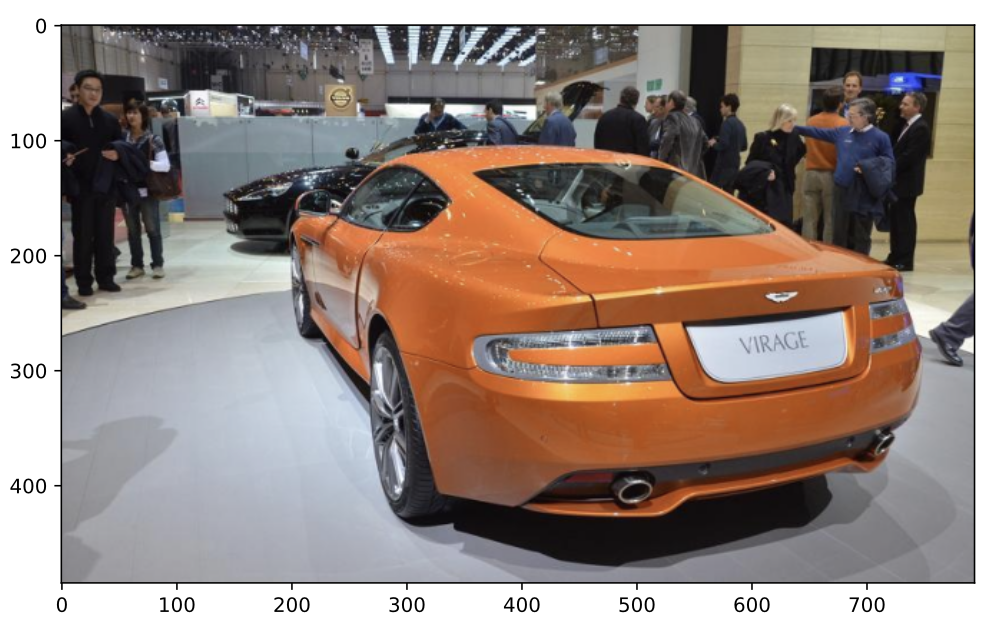
資料集已載入為 dataset。轉換已替你定義為 transforms,內容包含重新正規化與型別轉換。
本練習屬於課程
使用 Hugging Face 的多模態模型
練習說明
- 使用
.train_test_split()從dataset建立 80/20 的訓練/測試切分。 - 將轉換(
transforms)套用到data_splits。 - 從
dataset_transformed中第一組像素值繪製增強後的影像。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
# Create a train/test split within the HF dataset
data_splits = ____(test_size=____, seed=42)

# Apply the transformations
dataset_transformed = ____

# Plot the transformed image
plt.imshow(dataset_transformed["train"][0]["____"].permute(1, 2, 0))
plt.show()