使用 Vision Language Transformer(ViLT)的 VQA
現在來實作多模態生成,先從視覺問答(VQA)開始。你將使用 dandelin/vilt-b32-finetuned-vqa 模型,判斷下列影像中號誌的顏色:
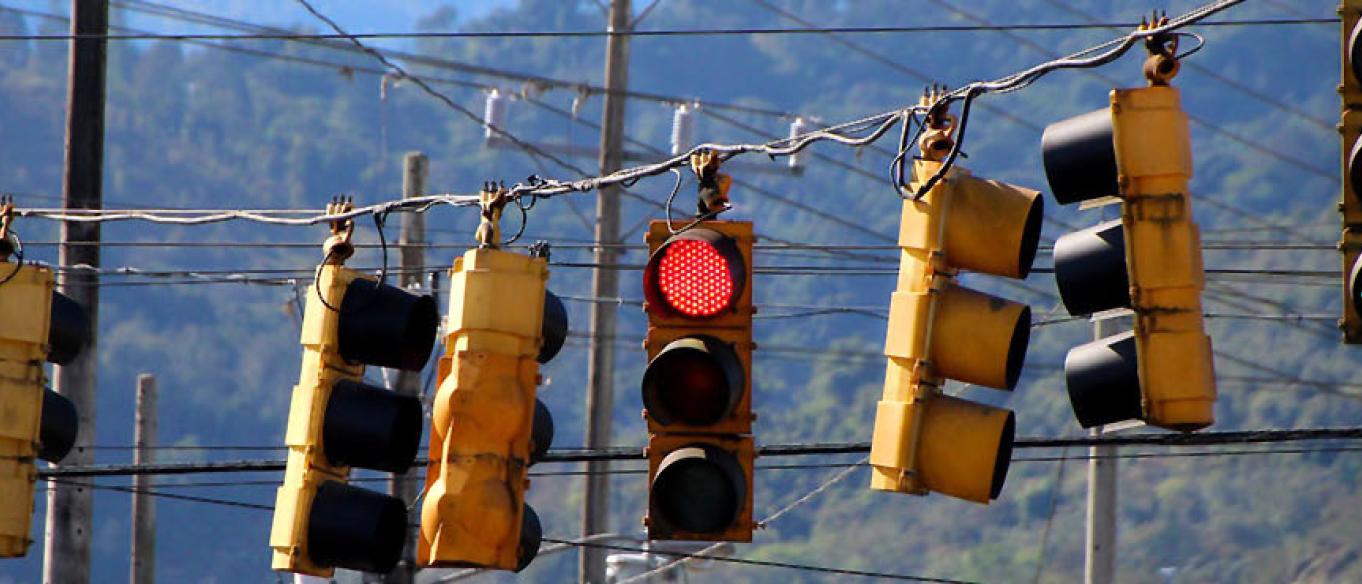
前處理器(processor)、模型(model)以及影像(image)都已為你載入。
本練習屬於課程
使用 Hugging Face 的多模態模型
練習說明
- 先對
text提示與image進行前處理。 - 從模型產生答案的權杖,並指定給
outputs。 - 使用輸出 logits,找出置信度最高的答案 ID。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
text = "What color is the traffic light?"

# Preprocess the text prompt and image
encoding = ____(____, ____, return_tensors="pt")

# Generate the answer tokens
outputs = ____

# Find the ID of the answer with the highest confidence
idx = outputs.logits.____
print("Predicted answer:", model.config.id2label[idx])