音訊去噪
在這個練習中,你會使用 WHAM 資料集的資料。該資料集將語音與背景雜訊混合;你的目標是產生一段以不同聲線說出的新語音,並且移除背景雜訊!
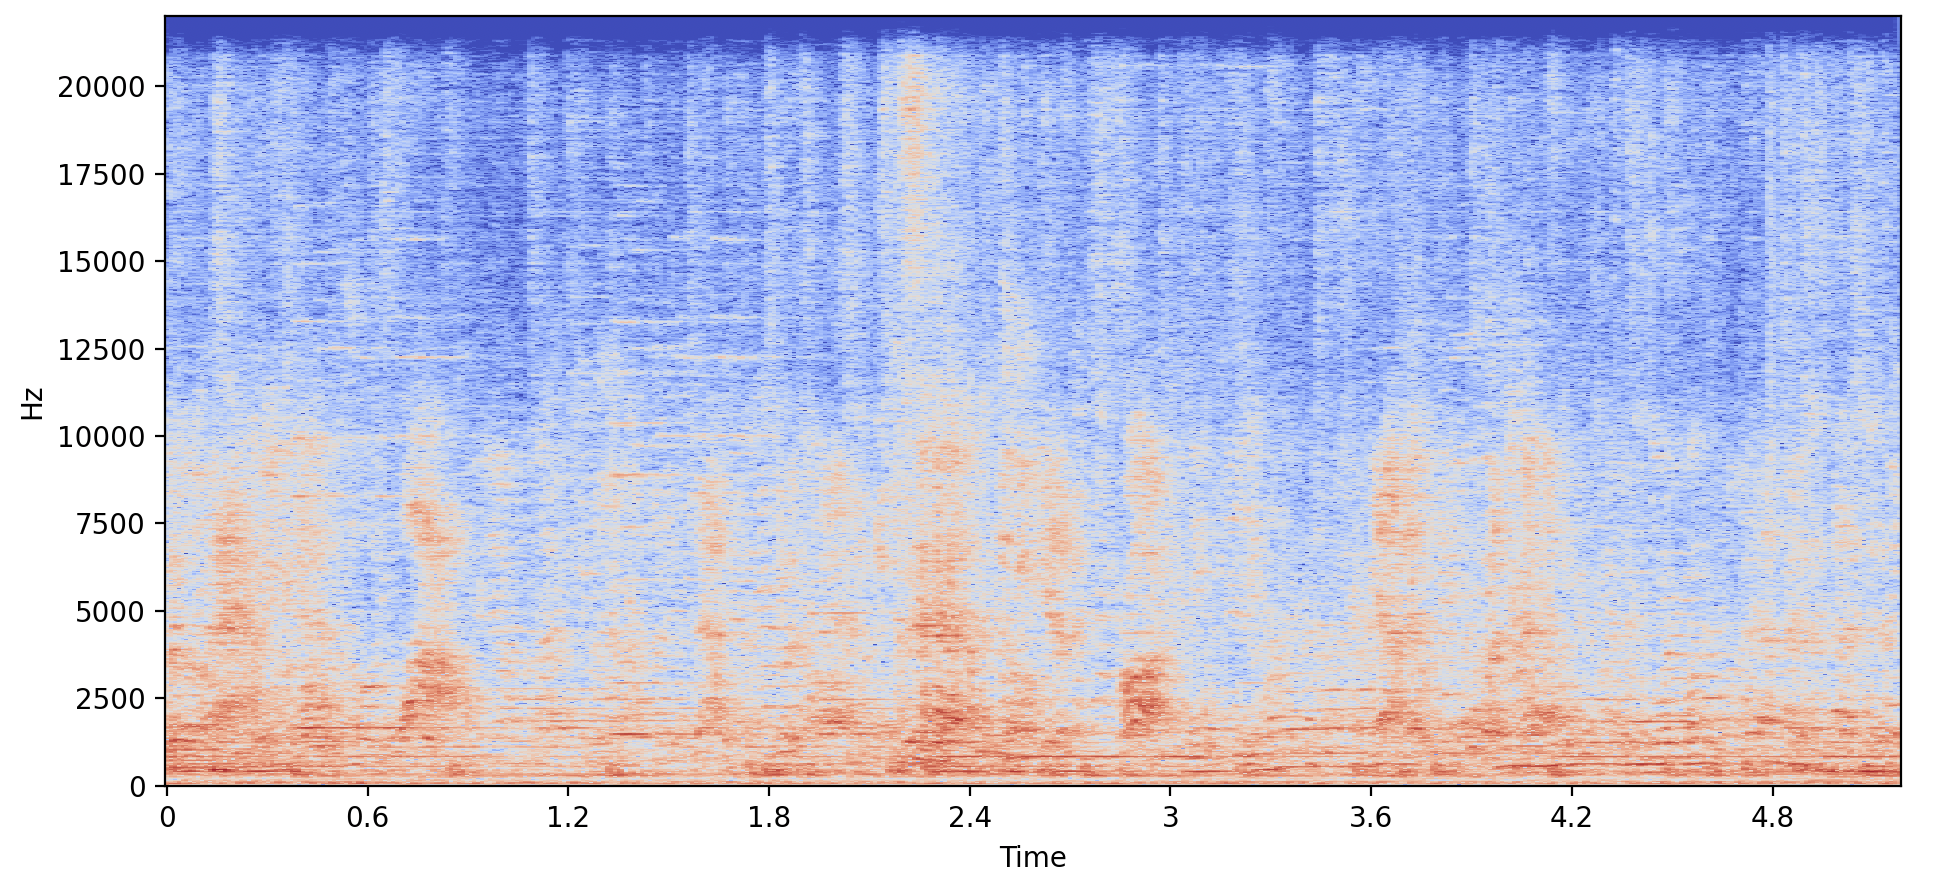
新的聲線所對應的 example_speech 陣列和 speaker_embedding 向量已經載入。前處理器(processor)與聲碼器(vocoder)也已可用,另外還有 SpeechT5ForSpeechToSpeech 模組。已提供 make_spectrogram() 函式來協助繪圖。
本練習屬於課程
使用 Hugging Face 的多模態模型
練習說明
- 使用
microsoft/speecht5_vc檢查點載入SpeechT5ForSpeechToSpeech的預訓練模型。 - 以取樣率
16000對example_speech進行前處理。 - 使用
.generate_speech()產生去噪後的語音。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
# Load the SpeechT5ForSpeechToSpeech pretrained model
model = ____

# Preprocess the example speech
inputs = ____(audio=____, sampling_rate=____, return_tensors="pt")

# Generate the denoised speech
speech = ____

make_spectrogram(speech)
sf.write("speech.wav", speech.numpy(), samplerate=16000)