使用 CLIP 與 CLAP 的影片情緒分析
現在你要使用 CLIP/CLAP 來分析先前準備的廣告情緒。為了進行多模態的情緒分類,你會將這些模型的預測取平均來結合(稱為「後期融合」late fusion)。
你先前建立的影片(video)與其對應的音訊(audio_sample)仍可使用:
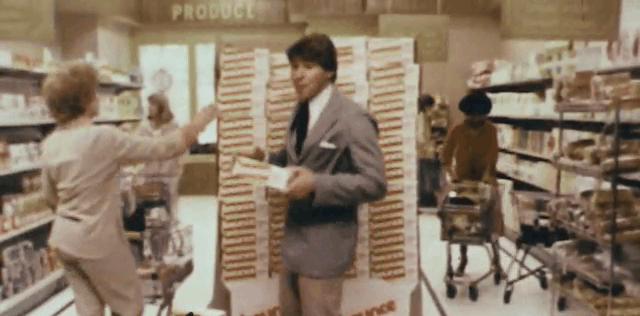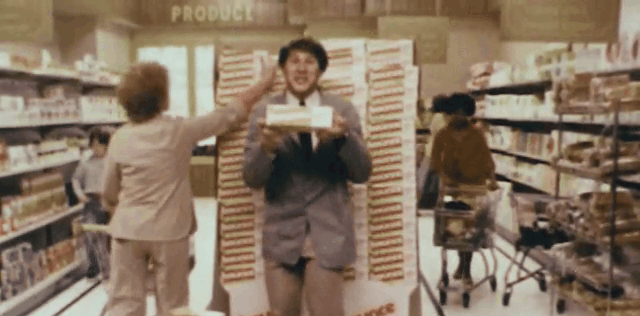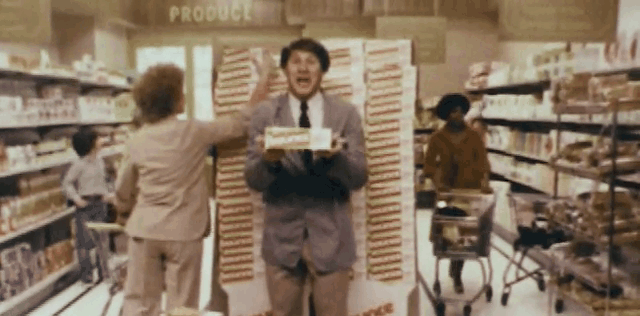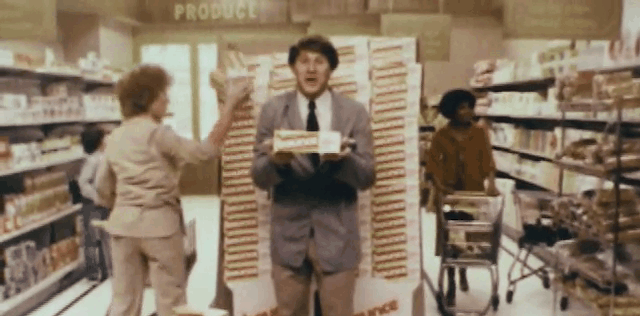
一份情緒清單已載入為 emotions。
本練習屬於課程
使用 Hugging Face 的多模態模型
練習說明
- 建立一個
zero-shot-audio-classification的音訊分類器 pipeline,使用模型laion/clap-htsat-unfused。 - 建立一個
zero-shot-image-classification的影像分類器 pipeline,使用模型openai/clip-vit-base-patch32(我們在影片中使用的模型之較小變體)。 - 使用影像分類器 pipeline 為影片中的每一張影格產生預測。
- 使用音訊分類器 pipeline 為
audio_sample產生預測。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
# Make an audio classifier pipeline
audio_classifier = ____(model="____", task="____")

# Make an image classifier pipeline
image_classifier = ____(model="____", task="____")

# Create emotion scores for each video frame
predictions = image_classifier(video, candidate_labels=emotions)
scores = [
    {l['label']: l['score'] for l in prediction}
    for prediction in predictions
]

avg_image_scores = {emotion: sum([s[emotion] for s in scores])/len(scores) for emotion in emotions}

# Make audio scores
audio_scores = ____(____, candidate_labels=____)

audio_scores = {l['label']: l['score'] for l in audio_scores}
multimodal_scores = {emotion: (avg_image_scores[emotion] + audio_scores[emotion])/2 for emotion in emotions}
print(f"Multimodal scores: {multimodal_scores}")