自訂圖片編輯
純文字生圖已經很厲害了,不過有些模型甚至支援自訂圖片編輯——這是一種多模態的影像產生方式,同時接受文字提示與來源圖片作為輸入。試著用 StableDiffusionControlNetPipeline 把這幅知名的梵谷自畫像改成卡通角色「史努比」吧:
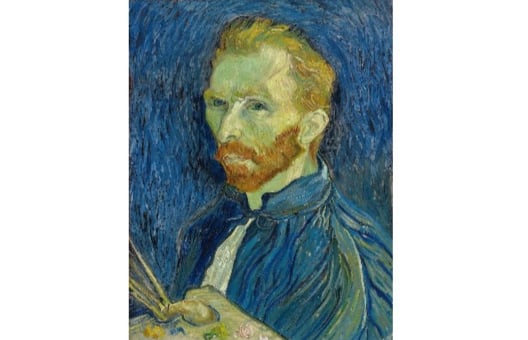
注意:擴散模型推論可能需要較長時間,因此我們已預先為你載入產生好的圖片。即使更換不同的提示詞,也不會產生新圖片。
已為你建立此圖片的 Canny 濾波版本(canny_image)。StableDiffusionControlNetPipeline 與 ControlNetModel 類別已從 diffusers 函式庫匯入。亂數產生器清單(generator)也已建立。
本練習屬於課程
使用 Hugging Face 的多模態模型
練習說明
- 從
lllyasviel/sd-controlnet-cannycheckpoint 載入ControlNetModel。 - 從
runwayml/stable-diffusion-v1-5checkpoint 載入StableDiffusionControlNetPipeline,並傳入提供的controlnet。 - 使用提供的
prompt、canny_image、negative_prompt與generator來執行 pipeline。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
## NOTE: no imports are required for this exercise
# Load a ControlNetModel from the pretrained checkpoint
controlnet = ____("____", torch_dtype=torch.float16)

# Load a pretrained StableDiffusionControlNetPipeline using the ControlNetModel
pipe = ____(
    "____", controlnet=____, torch_dtype=torch.float16
)
pipe = pipe.to("cuda")

prompt = ["Snoopy, best quality, extremely detailed"]

# Run the pipeline
output = pipe(
    ____,
    ____,
    negative_prompt=["monochrome, lowres, bad anatomy, worst quality, low quality"],
    generator=____,
    num_inference_steps=20,
)

plt.imshow(output.images[0])
plt.show()