使用 Pipeline 產生影像說明文字
在這個練習中,你會再次使用 flickr 資料集,它包含 30,000 張影像與對應的說明文字。這次你將改用 pipeline(而非 auto 類別)來為下列影像產生說明文字。
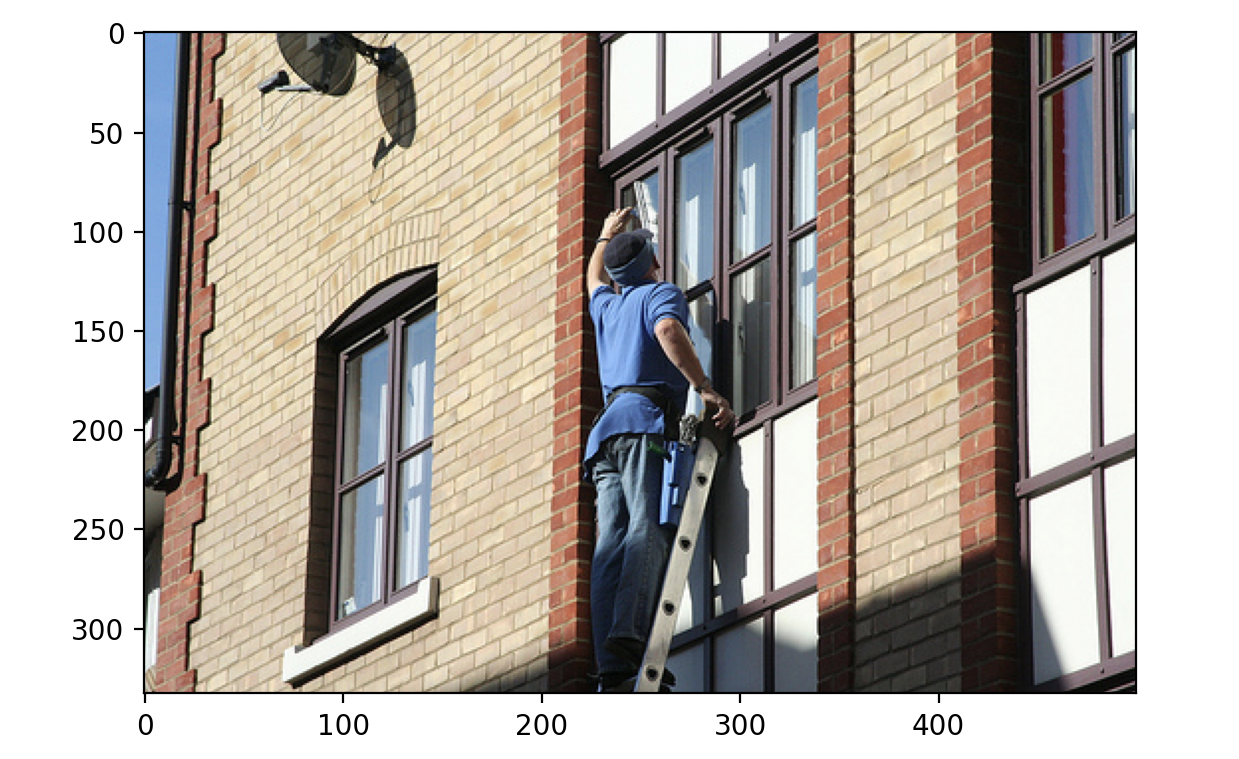
資料集(dataset)已載入,結構如下:
Dataset({
    features: ['image', 'caption', 'sentids', 'split', 'img_id', 'filename'],
    num_rows: 10
})
pipeline 模組(pipeline)已載入。
本練習屬於課程
使用 Hugging Face 的多模態模型
練習說明
- 載入
image-to-textpipeline,並使用Salesforce/blip-image-captioning-base預訓練模型。 - 使用該 pipeline 為索引為
3的影像產生說明文字。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
# Load the image-to-text pipeline
pipe = pipeline(task="____", model="____")

# Use the pipeline to generate a caption with the image of datapoint 3
pred = ____(dataset[3]["____"])

print(pred)