การ Prompt Vision Language Models (VLMs)
ในแบบฝึกหัดสองข้อถัดไป คุณจะใช้โมเดล multi-modal เพื่อวิเคราะห์ความรู้สึก (sentiment) ของบทความข่าวและภาพหัวข่าวที่เกี่ยวข้องจาก BBC News dataset บน Hugging Face:
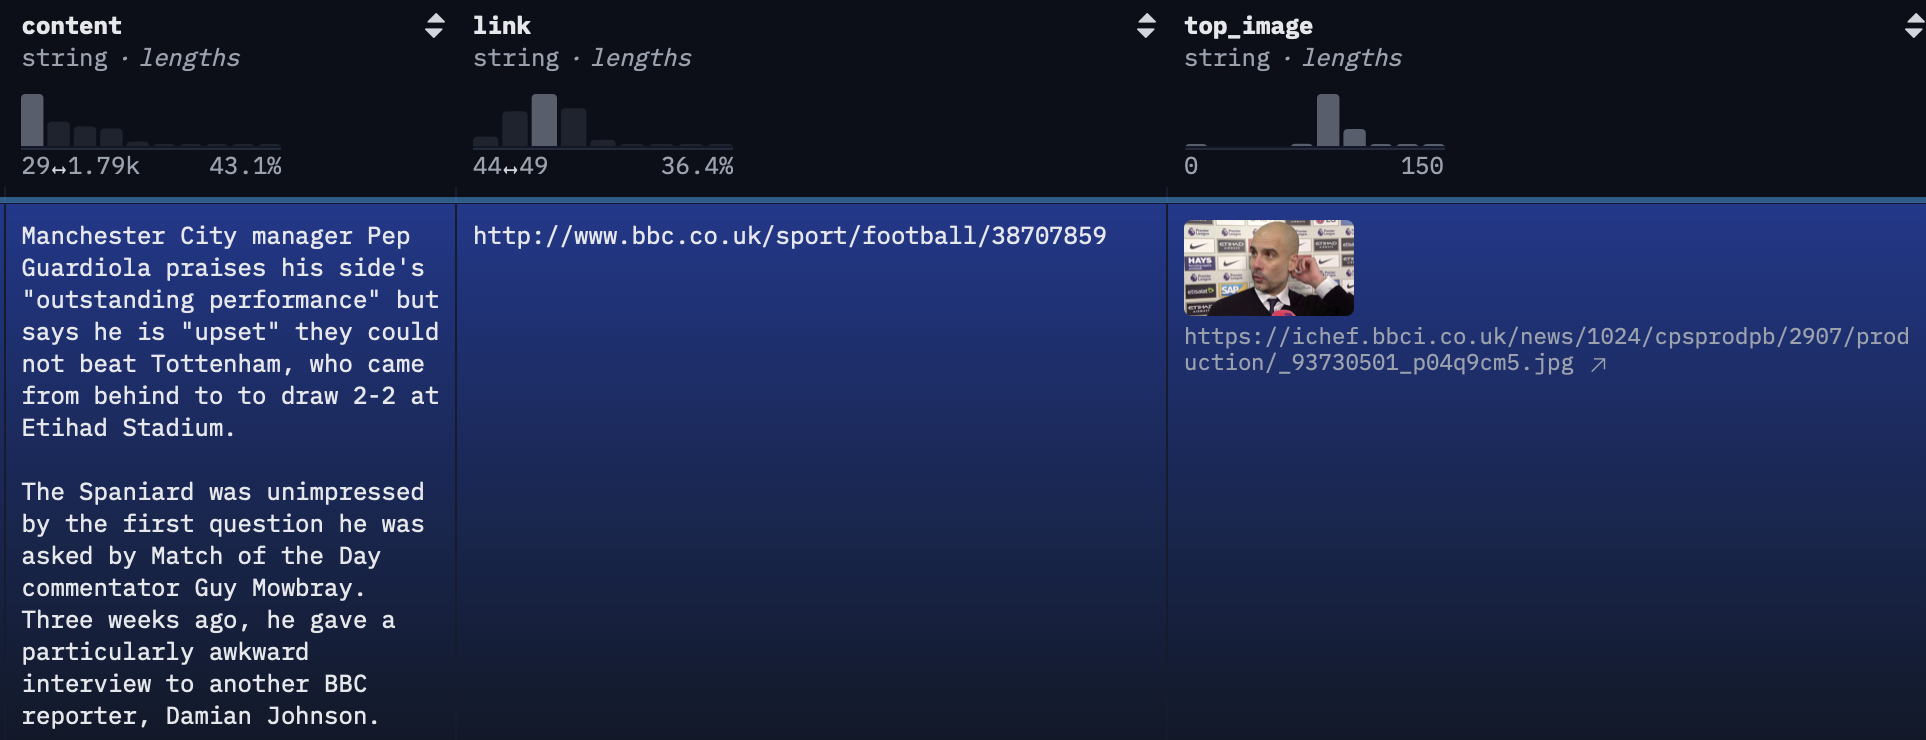
เริ่มต้นด้วยการเตรียม chat template สำหรับโมเดล โดยให้รวมทั้งภาพและบทความข่าวไว้ด้วยกัน ชุดข้อมูล (dataset) และภาพหัวข่าว (image) ถูกโหลดไว้แล้ว
แบบฝึกหัดนี้เป็นส่วนหนึ่งของหลักสูตร
โมเดล Multi-Modal ด้วย Hugging Face
คำแนะนำการฝึกหัด
- โหลดเนื้อหาบทความข่าว (
content) จาก datapoint ที่ index6ในdataset - เติมข้อความใน text query เพื่อแทรก
contentลงในtext_queryโดยใช้ f-string - เพิ่ม
imageและtext_queryลงใน chat template โดยระบุ content type ของtext_queryเป็น"text"
แบบฝึกหัดเชิงโต้ตอบแบบลงมือทำ
ลองทำแบบฝึกหัดนี้โดยเติมโค้ดตัวอย่างนี้ให้สมบูรณ์
# Load the news article content from datapoint 6
content = ____

# Complete the text query
text_query = f"Does the news article have a positive, negative, or neutral impact on championship winning chances: {____}. Provide reasoning."

# Add the text query dictionary to the chat template
chat_template = [
    {
        "role": "user",
        "content": [
            {
                "type": "image",
                "image": ____,
            },
            ____
        ],
    }
]