VQA ด้วย Vision Language Transformers (ViLTs)
มาลองใช้งาน multi-modal generation กัน โดยเริ่มต้นด้วย Visual Question-Answering (VQA) จะใช้โมเดล dandelin/vilt-b32-finetuned-vqa เพื่อระบุสีของสัญญาณไฟจราจรในภาพต่อไปนี้:
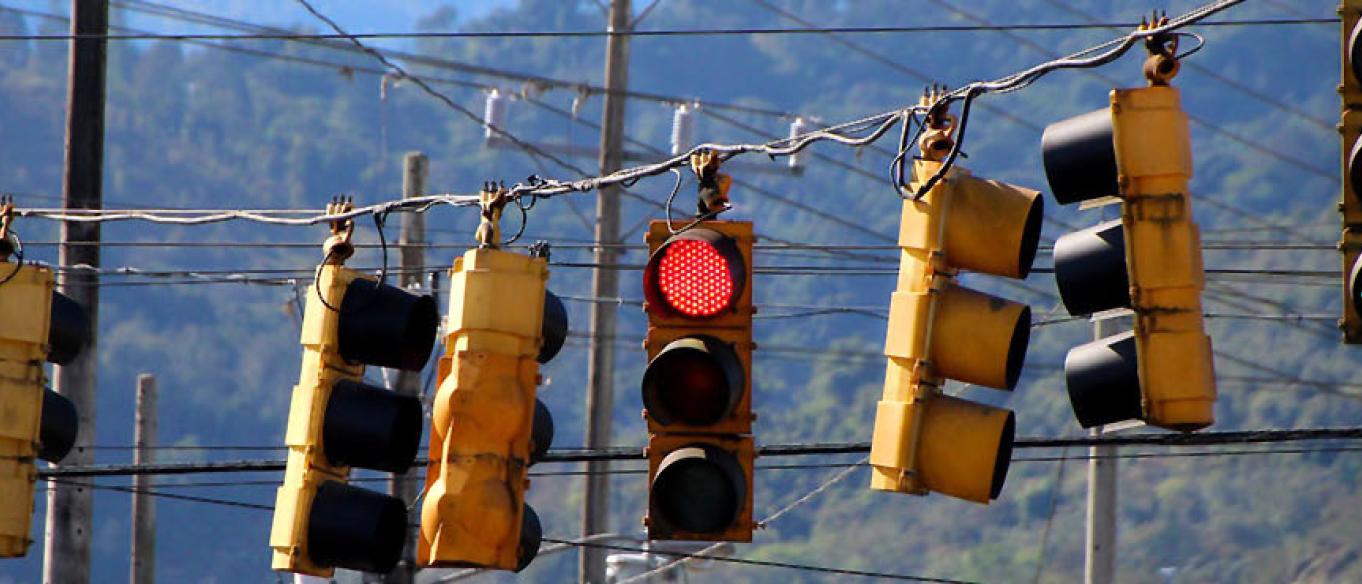
ตัวประมวลผลล่วงหน้า (processor), โมเดล (model) และภาพ (image) ถูกโหลดให้แล้ว
แบบฝึกหัดนี้เป็นส่วนหนึ่งของหลักสูตร
โมเดล Multi-Modal ด้วย Hugging Face
คำแนะนำการฝึกหัด
- ประมวลผลล่วงหน้า (preprocess)
textprompt และimage - สร้าง answer tokens จากโมเดล แล้วกำหนดค่าให้กับ
outputs - หา ID ของคำตอบที่มีความมั่นใจสูงสุดโดยใช้ output logits
แบบฝึกหัดเชิงโต้ตอบแบบลงมือทำ
ลองทำแบบฝึกหัดนี้โดยเติมโค้ดตัวอย่างนี้ให้สมบูรณ์
text = "What color is the traffic light?"

# Preprocess the text prompt and image
encoding = ____(____, ____, return_tensors="pt")

# Generate the answer tokens
outputs = ____

# Find the ID of the answer with the highest confidence
idx = outputs.logits.____
print("Predicted answer:", model.config.id2label[idx])