Zero-shot learning ด้วย CLIP
ในแบบฝึกหัดนี้จะใช้ zero-shot learning เพื่อจำแนกรูปภาพจากชุดข้อมูล rajuptvs/ecommerce_products_clip ซึ่งมีภาพสินค้าประมาณ 2,000 รายการพร้อมคำอธิบายที่เกี่ยวข้อง:
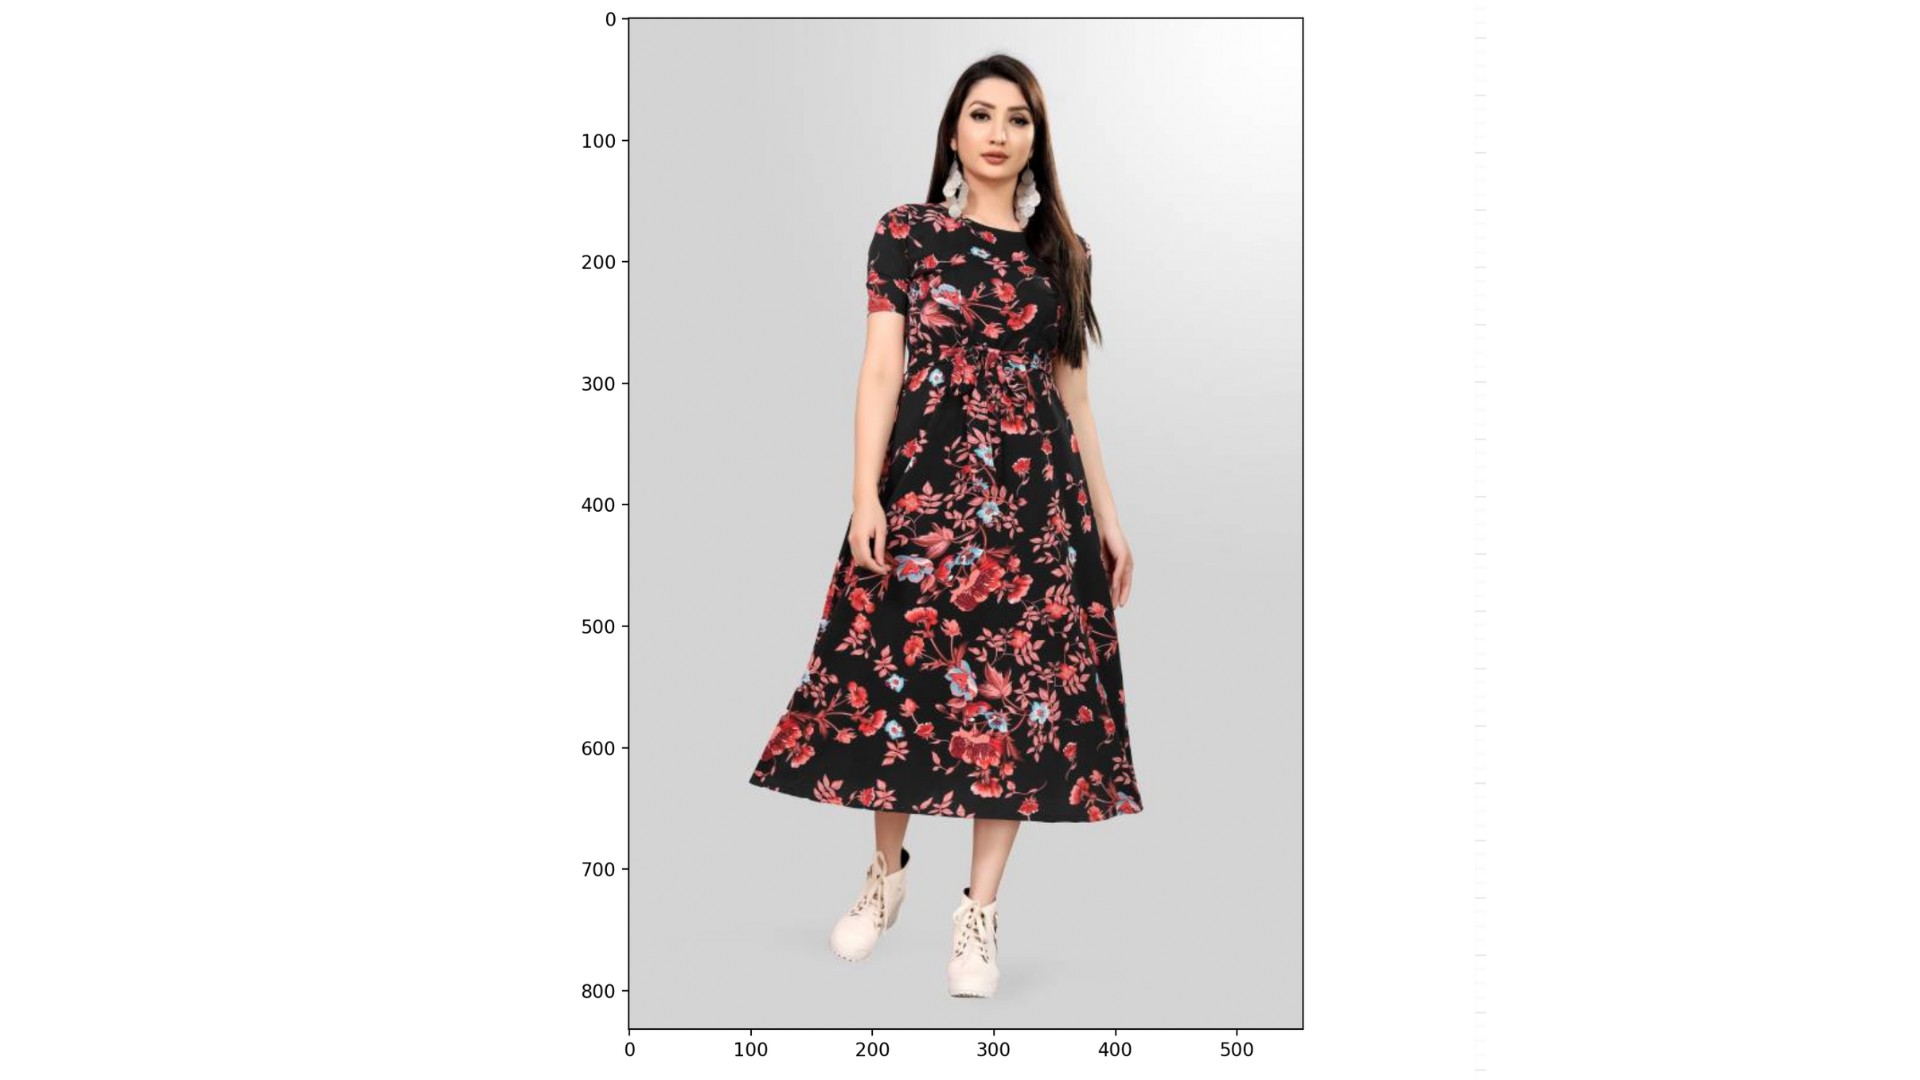
ชุดข้อมูล (dataset), CLIPProcessor (processor) และ CLIPModel (model) ถูกโหลดไว้ให้แล้ว พร้อมกับรายการหมวดหมู่ดังนี้:
categories = ["shirt", "trousers", "shoes", "dress", "hat",
              "bag", "watch", "glasses", "jacket", "belt"]
แบบฝึกหัดนี้เป็นส่วนหนึ่งของหลักสูตร
โมเดล Multi-Modal ด้วย Hugging Face
คำแนะนำการฝึกหัด
- ใช้
processorเพื่อประมวลผลcategoriesและรูปภาพที่ index999ของdatasetโดยเปิดใช้งาน padding - ส่ง
inputsที่ unpack แล้วเข้าสู่model - คำนวณค่าความน่าจะเป็นของแต่ละหมวดหมู่โดยใช้ attribute
.logits_per_imageและเมธอด.softmax() - ระบุหมวดหมู่ที่เป็นไปได้มากที่สุดโดยใช้
probsและcategories
แบบฝึกหัดเชิงโต้ตอบแบบลงมือทำ
ลองทำแบบฝึกหัดนี้โดยเติมโค้ดตัวอย่างนี้ให้สมบูรณ์
# Preprocess the categories and image
inputs = ____(text=____, images=____, return_tensors="pt", padding=____)

# Process the unpacked inputs with the model
outputs = ____

# Calculate the probabilities of each category
probs = outputs.____.____(dim=1)

# Find the most likely category
category = categories[probs.____.item()]
print(f"Predicted category: {category}")