電動滑板車社群的情緒分析
市議會想了解市內不同社群對電動滑板車的反應如何。 自從 Sam 最初的分析之後,資料集已經擴充,現在包含越南語、他加祿語、西班牙語與英語的回報。
他們請 Sam 看看能不能找出一些端倪。她決定先用語言當作社群的代理變數(至少在她眼前可取得的資料裡可行)。
她已經把 CSV 載入到變數 scooter_df:
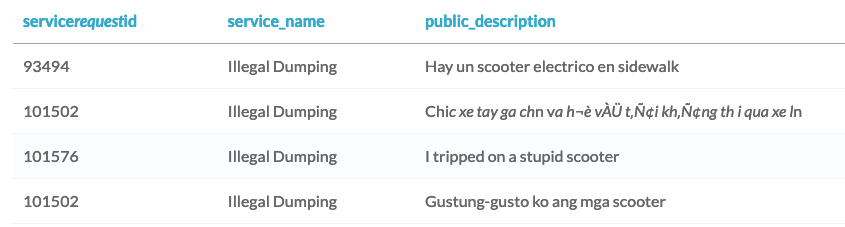
在這個練習中,你會協助 Sam 了解多種語言的情緒傾向。這能幫助市府理解不同社群如何看待電動滑板車,進而影響市議員的投票。
本練習屬於課程
Python 中的 AWS Boto 入門
練習說明
- 對於每一列 DataFrame,偵測主導語言。
- 使用偵測到的語言來判定描述文字的情緒。
- 依序以
'sentiment'與'lang'欄位彙總(groupby)整個 DataFrame。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
for index, row in scooter_requests.iterrows():
  	# For every DataFrame row
    desc = scooter_requests.loc[index, 'public_description']
    if desc != '':
      	# Detect the dominant language
        resp = comprehend.____(____=desc)
        lang_code = resp['Languages'][0]['LanguageCode']
        scooter_requests.loc[index, 'lang'] = lang_code
        # Use the detected language to determine sentiment
        scooter_requests.loc[index, 'sentiment'] = comprehend.____(
          ____=desc,
          ____=lang_code)['____']
# Perform a count of sentiment by group.
counts = scooter_requests.groupby(['sentiment', 'lang']).count()
counts.head()