策略網路架構
建立一個之後可用來訓練策略梯度代理人的策略網路架構。
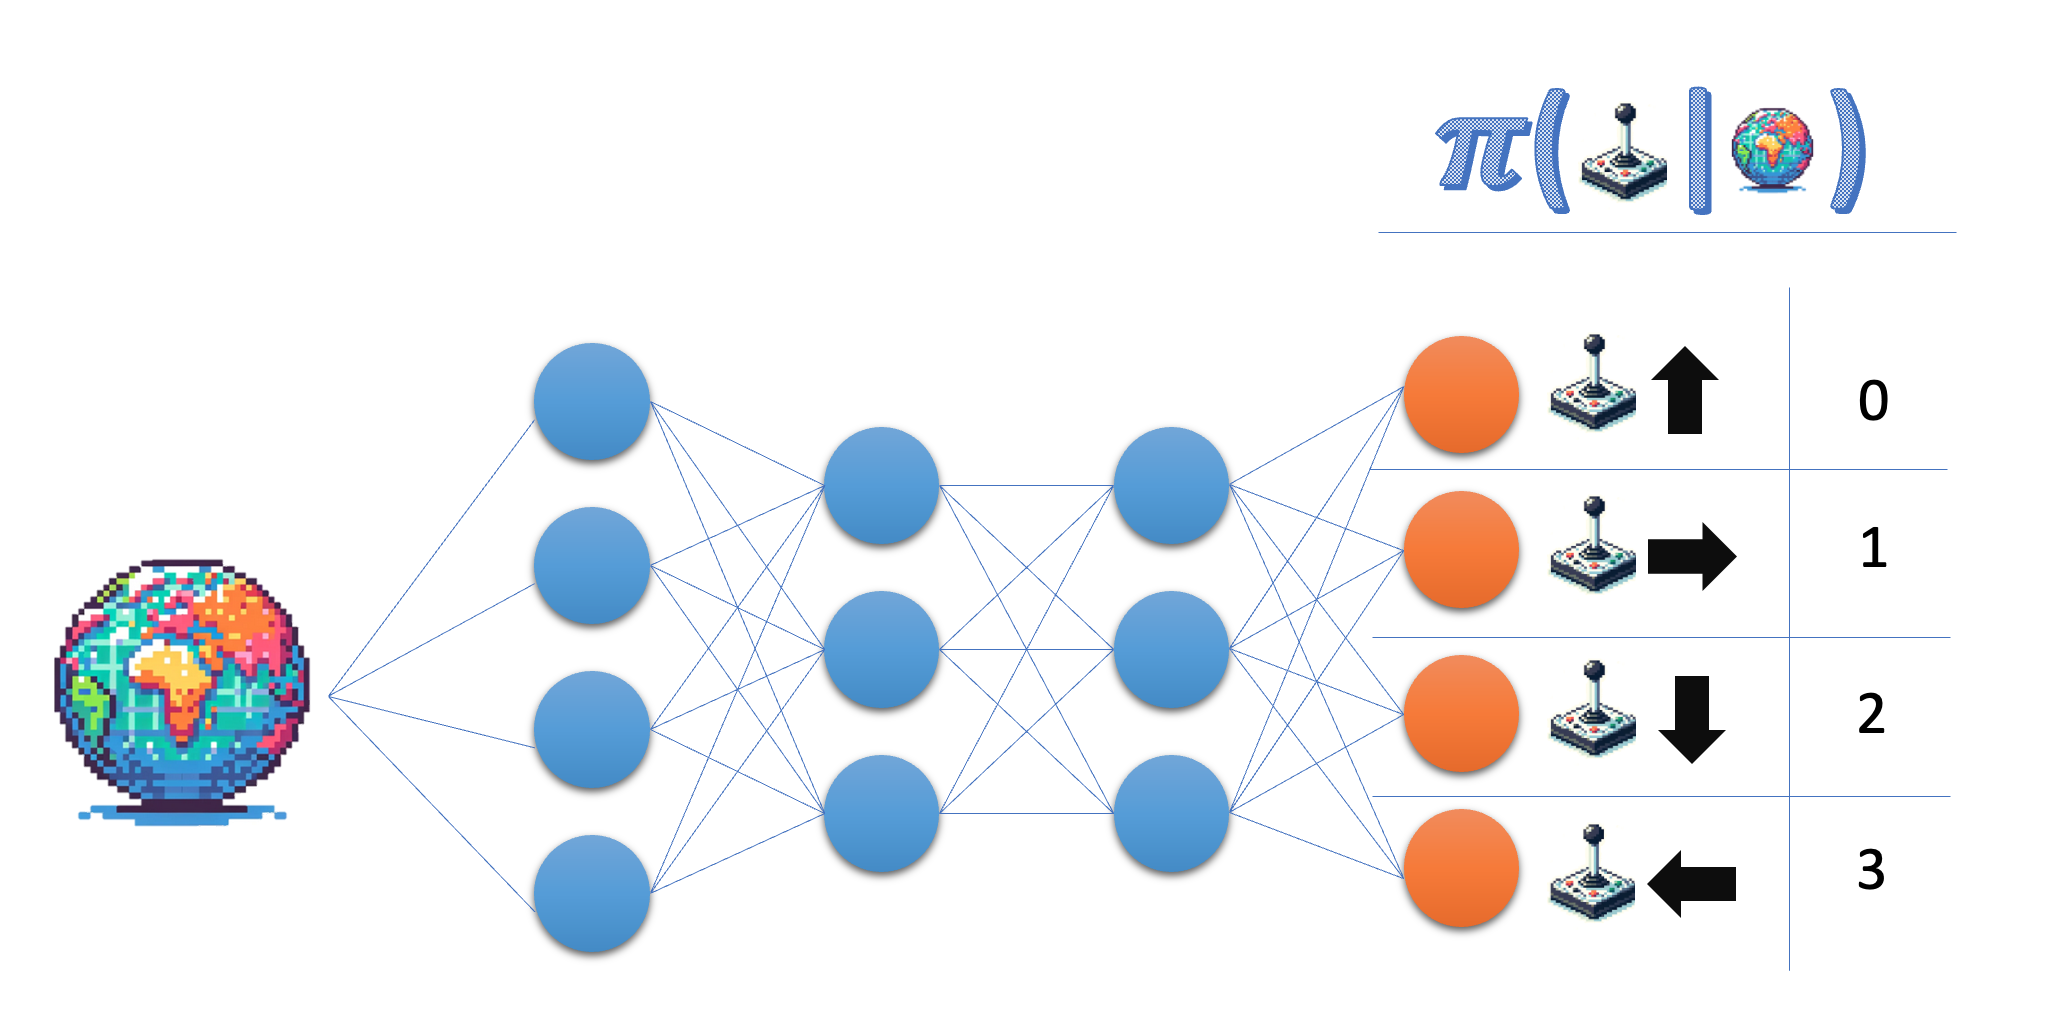
策略網路以狀態作為輸入,並在動作空間中輸出機率。以 Lunar Lander 環境為例,你會處理 4 個離散動作,因此你要讓網路為每個動作各輸出一個機率。
本練習屬於課程
Python 的深度強化學習
練習說明
- 指定策略網路輸出層的大小;為了彈性,請使用變數名稱而非直接填入數字。
- 確保最後一層回傳的是機率。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
class PolicyNetwork(nn.Module):
  def __init__(self, state_size, action_size):
    super(PolicyNetwork, self).__init__()
    self.fc1 = nn.Linear(state_size, 64)
    self.fc2 = nn.Linear(64, 64)
    # Give the desired size for the output layer
    self.fc3 = nn.Linear(64, ____)

  def forward(self, state):
    x = torch.relu(self.fc1(torch.tensor(state)))
    x = torch.relu(self.fc2(x))
    # Obtain the action probabilities
    action_probs = ____(self.fc3(x), dim=-1)
    return action_probs

policy_network = PolicyNetwork(8, 4)
action_probs = policy_network(state)
print('Action probabilities:', action_probs)