精簡版 DQN 損失函式
現在 select_action() 已就緒,你只差最後一步就能訓練你的代理人了:接下來你要實作 calculate_loss()。
calculate_loss() 會回傳該回合任一步驟對應的網路損失。
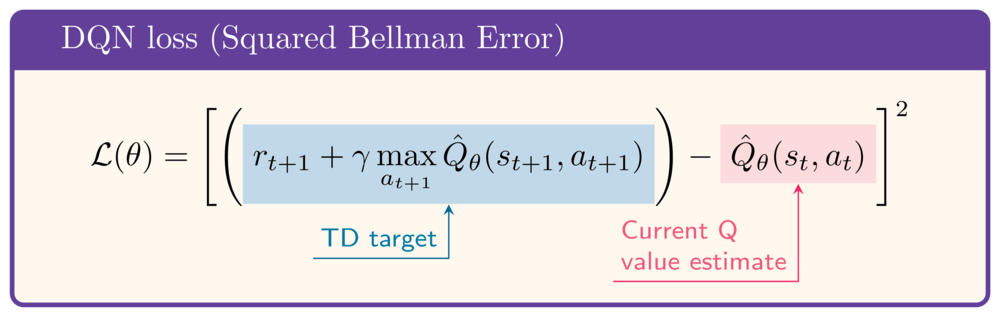
作為參考,損失定義如下:
下列範例資料已在本練習中載入:
state = torch.rand(8)
next_state = torch.rand(8)
action = select_action(q_network, state)
reward = 1
gamma = .99
done = False
本練習屬於課程
Python 的深度強化學習
練習說明
- 取得目前狀態的 Q 值。
- 取得下一狀態的 Q 值。
- 計算目標 Q 值(TD-target)。
- 計算損失函式,也就是平方的 Bellman 誤差。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
def calculate_loss(q_network, state, action, next_state, reward, done):
    q_values = q_network(state)
    print(f'Q-values: {q_values}')
    # Obtain the current state Q-value
    current_state_q_value = q_values[____]
    print(f'Current state Q-value: {current_state_q_value:.2f}')
    # Obtain the next state Q-value
    next_state_q_value = q_network(next_state).____
    print(f'Next state Q-value: {next_state_q_value:.2f}')
    # Calculate the target Q-value
    target_q_value = ____ + gamma * ____ * (1-done)
    print(f'Target Q-value: {target_q_value:.2f}')
    # Obtain the loss
    loss = nn.MSELoss()(____, ____)
    print(f'Loss: {loss:.2f}')
    return loss

calculate_loss(q_network, state, action, next_state, reward, done)