訓練一棵決策樹
隨機森林是做預測時常用的模型,通常開箱即用就有不錯的表現。不過在進入隨機森林之前,我們先了解它的基礎組件──決策樹。
決策樹會根據特徵把資料切分成不同群組。它從根節點開始,一路往下切分,直到到達葉節點為止。
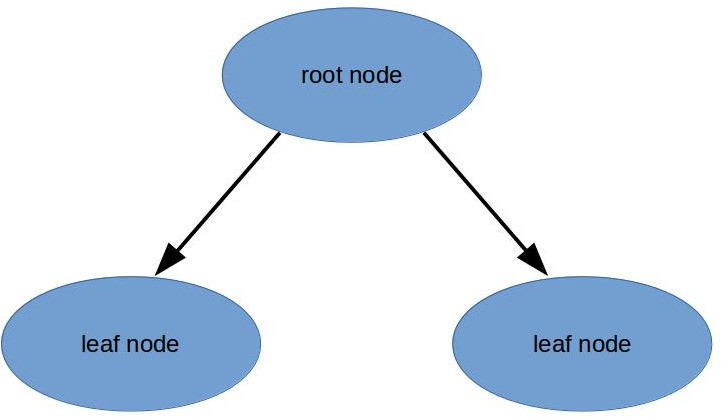
我們可以用 sklearn 的 DecisionTreeRegressor,搭配 .fit(features, targets) 來訓練一棵決策樹。
如果不限制樹的深度(或高度),模型會一直切分資料,直到每個葉節點只剩 1 個樣本,這就是典型的過度擬合。我們會在後面的章節更深入探討過度擬合。
本練習屬於課程
Python 金融 Machine Learning
練習說明
- 使用已匯入的
DecisionTreeRegressor類別,採用預設參數(也就是不用傳入參數),建立名為decision_tree的決策樹模型。 - 使用先前建立的
train_features和train_targets(目前包含星期幾與成交量等特徵)來訓練模型。 - 分別列印模型在訓練特徵與目標、以及在
test_features和test_targets上的分數。
動手互動練習
試著完成這個範例程式碼,體驗一下這個練習。
from sklearn.tree import DecisionTreeRegressor

# Create a decision tree regression model with default arguments
decision_tree = ____

# Fit the model to the training features and targets
decision_tree.fit(____)

# Check the score on train and test
print(decision_tree.score(train_features, train_targets))
print(decision_tree.score(____))